Platform operations
Day-to-day stewardship of compute, networks, and managed services - with clear ownership, runbooks, and a change process that does not rely on heroics.
Infrastructure Management
Agam Studio runs and stewards the infrastructure your products depend on - environments, monitoring, patching, and the operational habits that keep incidents rare and recoverable. We treat uptime as a product, not a ticket queue.
Build
Stewardship for systems that already have users.
Infrastructure that only the original engineer understands is a business risk. Many teams struggle with alert noise, unpatched estates, and environments that cannot be rebuilt. Agam Studio takes ownership of platform operations - observability, change, security baselines, and cost - so your product team can ship features without babysitting servers.
Day-to-day stewardship of compute, networks, and managed services - with clear ownership, runbooks, and a change process that does not rely on heroics.

Alerts that mean something, on-call that is survivable, and post-incident habits that change the system instead of blaming the person who was awake.

Dev, staging, and production that match closely enough to be useful. We reduce “it worked in staging” by treating environment drift as a defect.

Baselines, patch windows, and access control that auditors can follow. Security work is scheduled into operations, not saved for the week after a CVE hits the news.

Capacity, reserved instances, and idle resource hygiene so the bill tracks usage. We make spend visible to the people who can actually change it.

A regulated fintech needed to replatform core services while keeping audit trails intact and releases predictable.
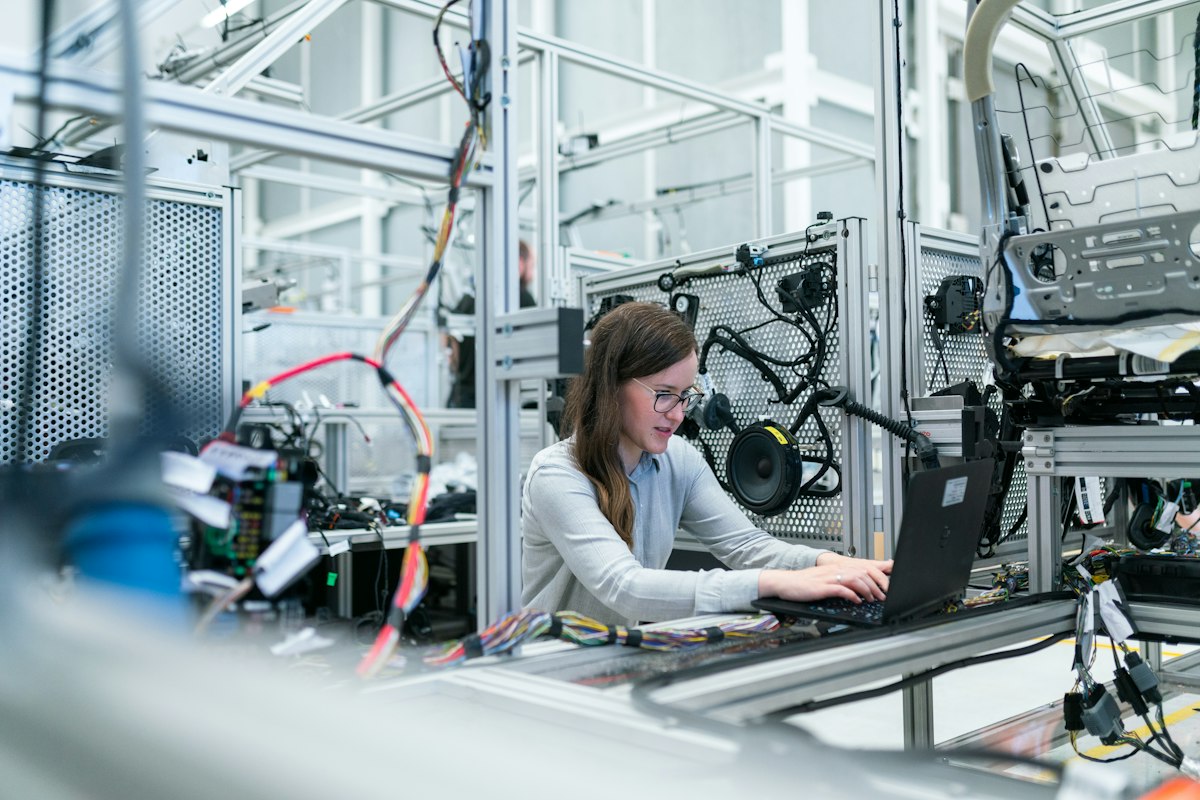
A manufacturer connected shop-floor sensors to operations dashboards with practical OT/IT boundaries.
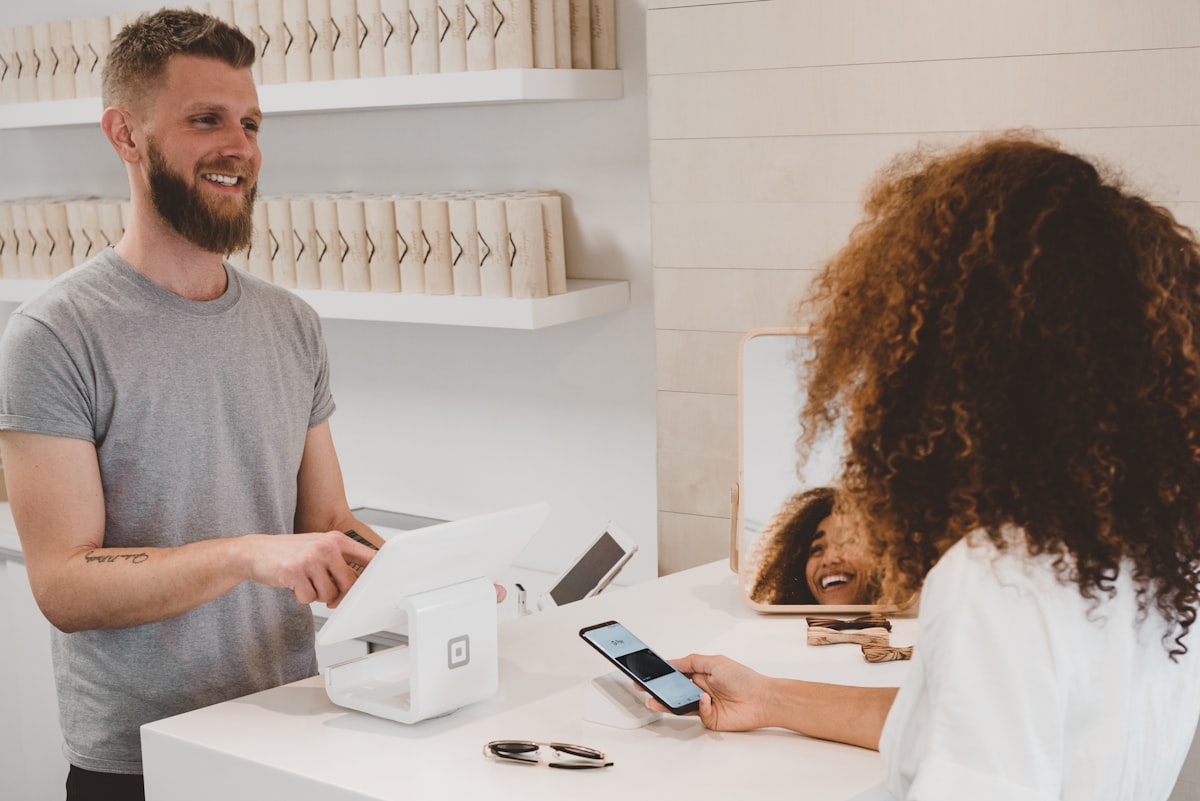
A commerce brand tightened CI/CD, observability, and squad practices ahead of their busiest quarter.
Stable environments and a change process the business can plan around - not surprise weekends.
Patching, access control, and monitoring that hold up in audit and in an incident.
Improve the estate in slices while live products keep running.
Future-ready product teams design for change from the start-scalability, portability, and incremental evolution-not a full rewrite every few years. This article walks through the signals most organisations miss and a practical framework for assessing whether your stack can support the next three years of growth.
Read the articleWhen delivery slows, incidents cluster, and retrospectives start sounding the same, the problem is often systemic-not individual. This article covers the earliest warning signs and what an independent technical audit should examine across people, process, and platform.
Read morePressure to ship AI pilots is real, but teams that skip strategy stall on unclear ROI, messy data, and governance gaps. This article explains why use-case clarity, data readiness, and guardrails must come before model selection-and how governance can actually accelerate adoption.
Read the article